Real-Time Agents
& Deep Research
One stack for deep research agents.
Live Search, page reads, PDF parsing at scale, and cited academic evidence.
companies of all sizes


Perfect for
AI labs shipping a deep research feature
Give the deep-research surface of your product a web backend that already handles Search, scraping, heavy PDFs, and cited evidence, so you ship one integration instead of a multi-vendor patchwork.
Agent harness builders
Wire Firecrawl into a custom agent harness and outperform the default deep-research cookbook, without spending a quarter on Playwright glue and proxy rotation.
Answer engines and RAG products
Keep vector stores fresh and citations honest with clean Markdown, preserved URLs, and diff alerts when the source page moves.
Consulting and strategy teams
Turn a scoping question into a source-backed brief without the weeks of manual collection that usually sits at the start of a study.
Market and competitive analysis
Track competitors, categories, and themes across public sources and get pinged when a launch, pricing move, or disclosure lands.
Academic and technical research
Anchor claims in citation-ready passages from the Firecrawl Research Index across arXiv and a life sciences corpus, plus deep-PDF handling for the filings and papers that break lighter tools.
How it works
Kick off with live web Search
Have your agent call Firecrawl Search to find the right URLs for each question, so the source list reflects what is actually online today.
Read the sources with Scrape and Crawl
Scrape a single URL or Crawl a whole domain and Firecrawl returns clean Markdown or JSON with URL, title, and timestamp preserved on every chunk.
Cover the documents with Parse
Send PDFs, DOCX, XLSX, and HTML files to Parse and Firecrawl returns layout-aware Markdown. Heavy enterprise research workloads lean on this path for filings, whitepapers, and analyst reports.
Ground academic and technical claims in the Research Index
Query the Firecrawl Research Index across 3M+ arXiv papers plus a life sciences corpus for citation-ready passages, metadata, and citation-graph traversal.
Refresh long-running studies with Monitor
Point Monitor at the sources that back a study and set a schedule. An AI judge fires a webhook only when something meaningful changes.
Let an Agent drive multi-step research end to end
Firecrawl Agent takes a plain-language task, plans the steps, and calls Search, Scrape, Crawl, and Parse across many sources. Teams building a custom harness on top regularly beat the default deep-research cookbook.
People love
building with Firecrawl


Firecrawl is an open-source framework that takes a URL, crawls it, and conver..."

Upload a CSV of emails and..."
Firecrawl is an open-source framework that takes a URL, crawls it, and conver..."
Upload a CSV of emails and..."
How Firecrawl compares to alternatives
| Feature | Firecrawl | Manual CSV uploads | Browser extensions | Generic scrapers |
|---|---|---|---|---|
| Structured markdown output | Yes | No | No | No |
| Automatic scheduling & refresh | Yes | No | No | Yes |
| One vendor for search, scrape, browse, and parse | Yes | No | No | No |
| Zero Data Retention available on enterprise | Yes | No | No | No |
| Document parsing (PDF, DOCX, XLSX) | Yes | No | No | No |
| Cited academic passages (Research Index) | Yes | No | No | No |
| Change monitoring with AI-filtered alerts | Yes | No | No | No |
| Agent-driven multi-step research | Yes | No | No | No |
| JavaScript rendering | Yes | No | Yes | No |
| URL metadata preserved | Yes | No | No | No |
| Multi-tenant scoping | Yes | No | No | No |
| API-first integration | Yes | No | No | Yes |
| Built-in rate limiting & retries | Yes | No | No | No |
| No manual intervention required | Yes | No | No | No |
All Customer Stories
How Stanford's AI Playground Covers 10,000+ Domains for Real-Time LLM Grounding
AI Playground serves the Stanford community by augmenting LLM responses with real-time web data across 10,000+ domains, processing about 800 sources daily using Firecrawl's Search and Scrape endpoints.
How Athena Intelligence Empowers Enterprise Analysts with Firecrawl
Discover how Athena Intelligence leverages Firecrawl to fuel its AI-native analytics platform for enterprise analysts.
Tutorials & guides
Web Search and Deep Research for AI Agents: What It Is and How to Integrate It into Your Agentic Stack
Learn what web search and deep research mean for AI agents, why 2026 made both production-grade, and how to wire them into your stack with Firecrawl.
Read tutorial →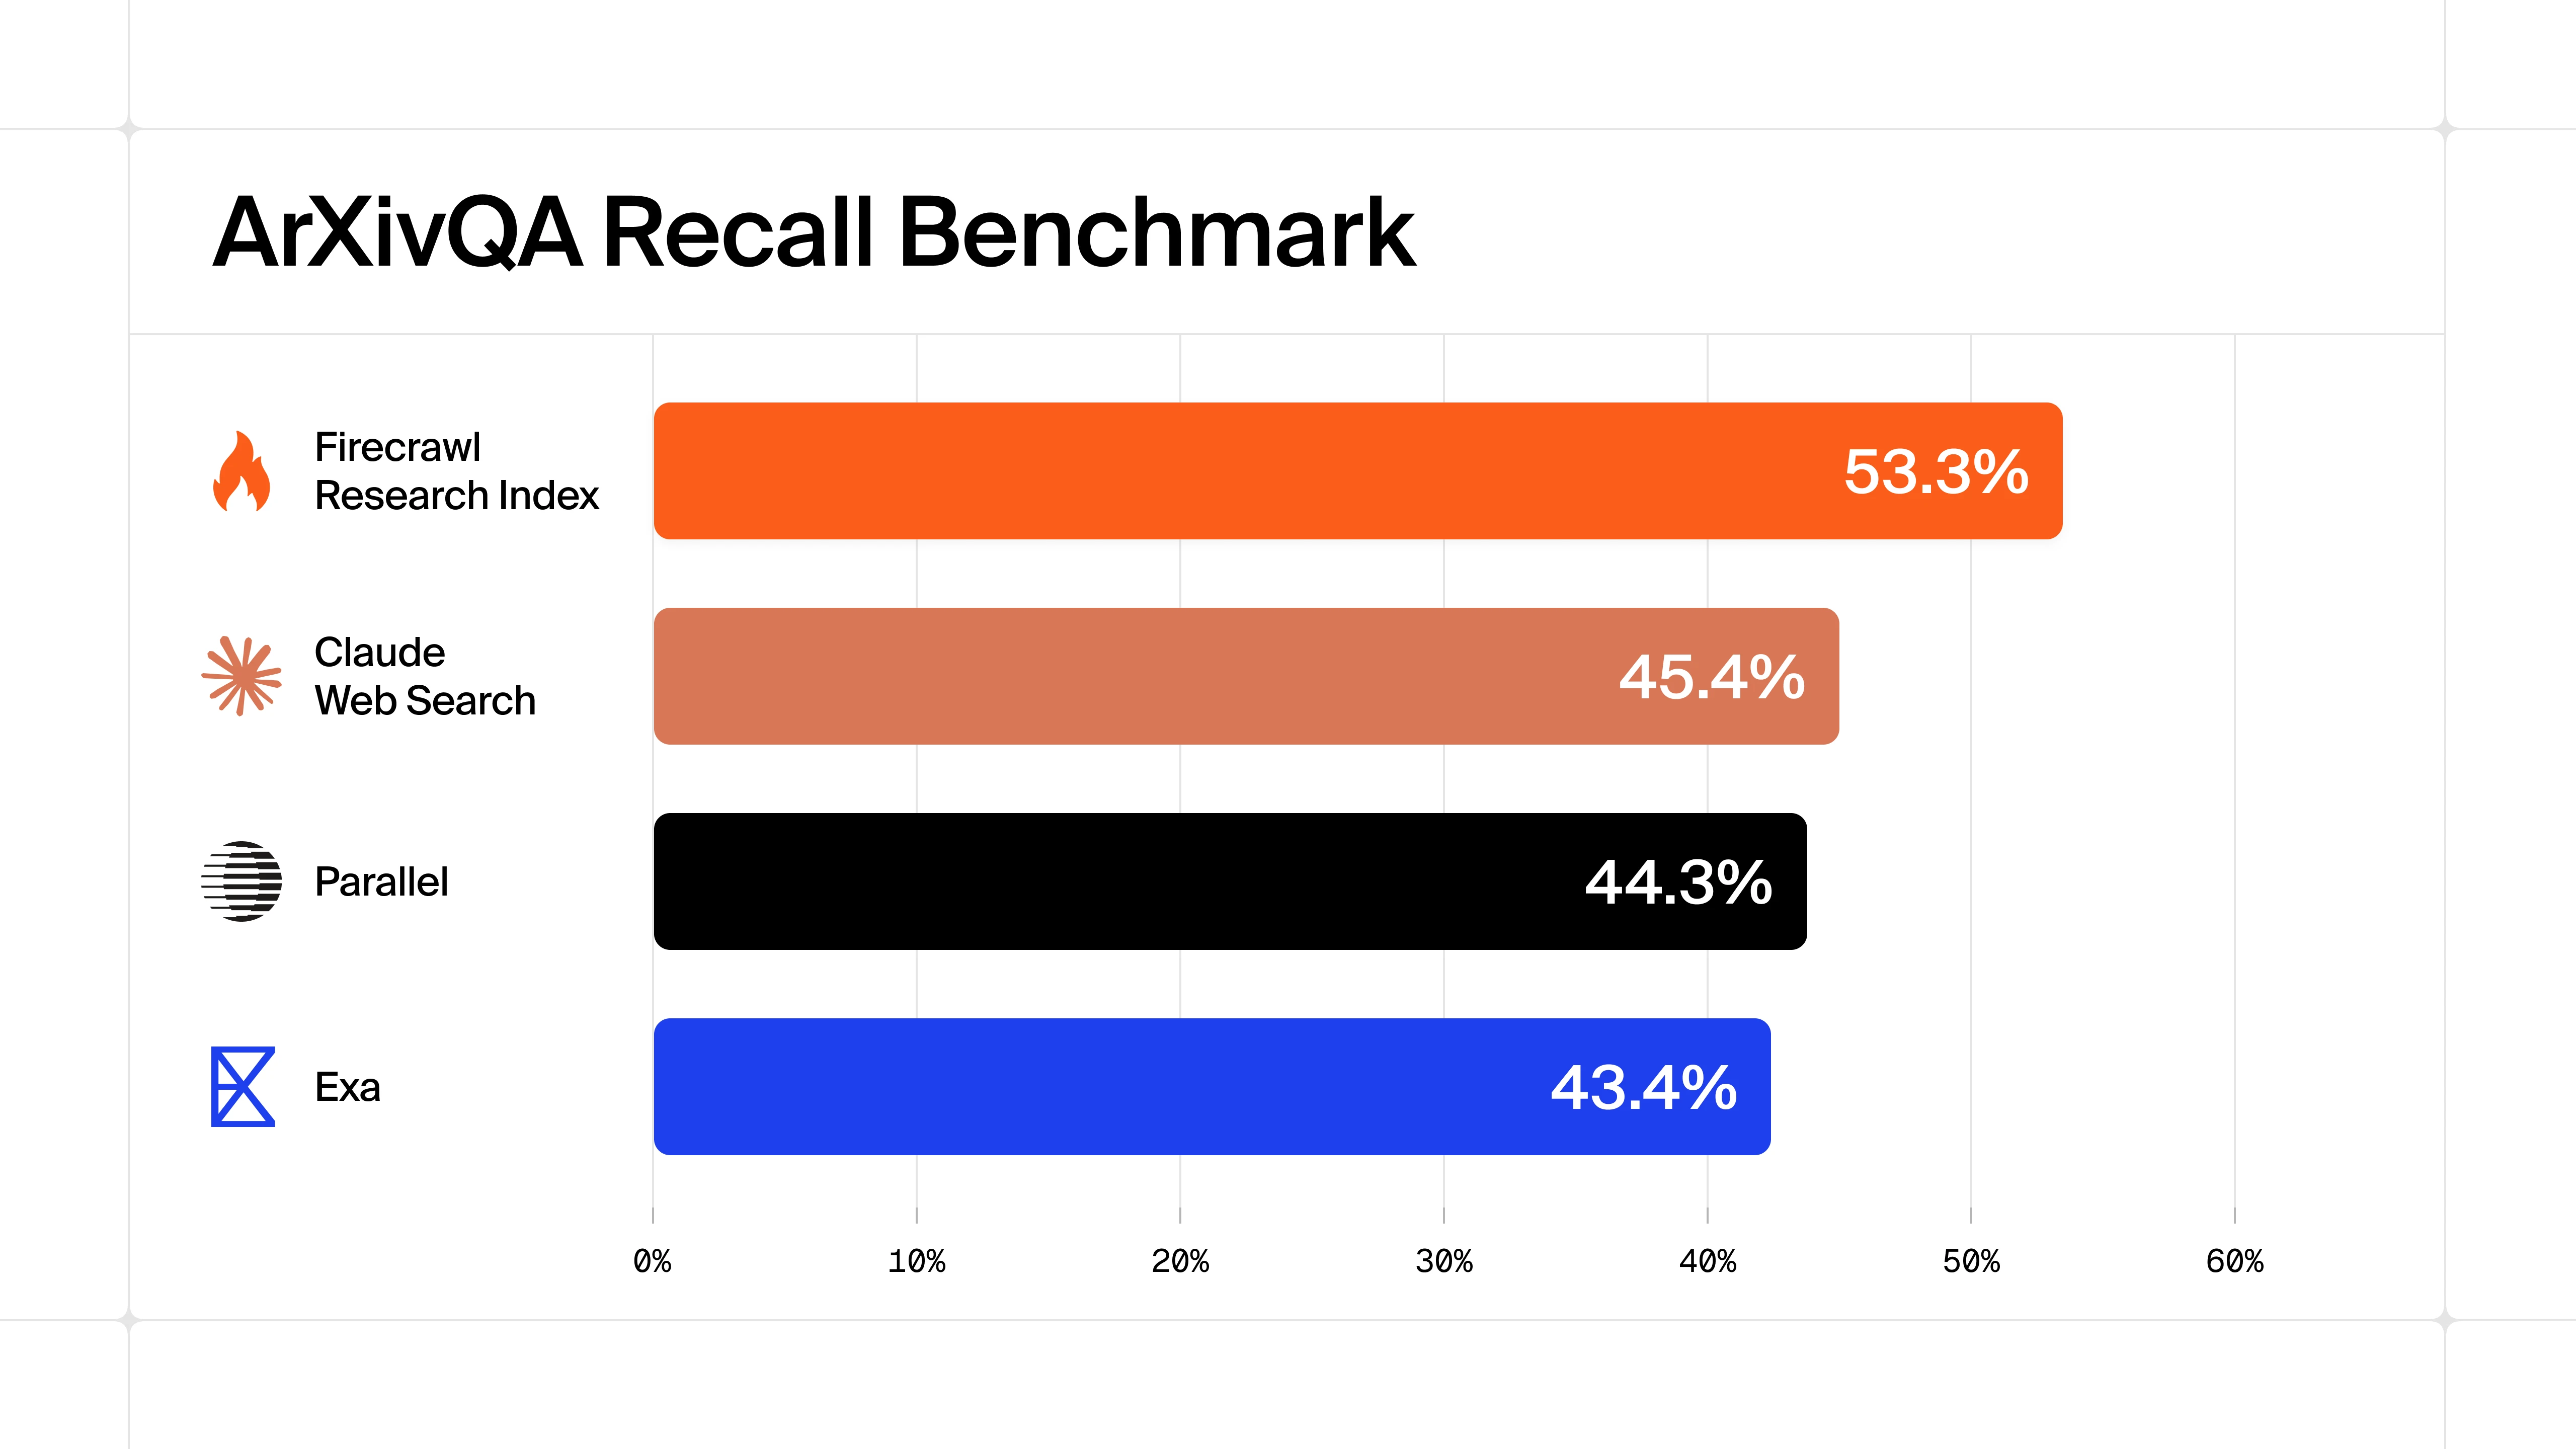
Introducing Firecrawl Research Index: a specialized index for agentic AI/ML research
Firecrawl Research Index gives agents the entire AI/ML literature and the code behind it, with SOTA recall on arXivQA, 18% above the next best provider at comparable cost.
Read tutorial →
How AI Agents Can Reliably Search Academic Papers in 2026
Compare five academic search APIs for AI agents, with current rate limits, retrieval tradeoffs, TypeScript examples, and real Firecrawl output.
Read tutorial →
Frequently
asked questions
Flexible pricing
Free Plan
Hobby
StandardMost popular
Growth
Scale Plans
High-volume plans for teams that need more power and dedicated support. Get access to higher rate limits, more concurrent browsers, and priority support. Scale checks out instantly, no sales call needed.
Need more? Contact us